21 min read
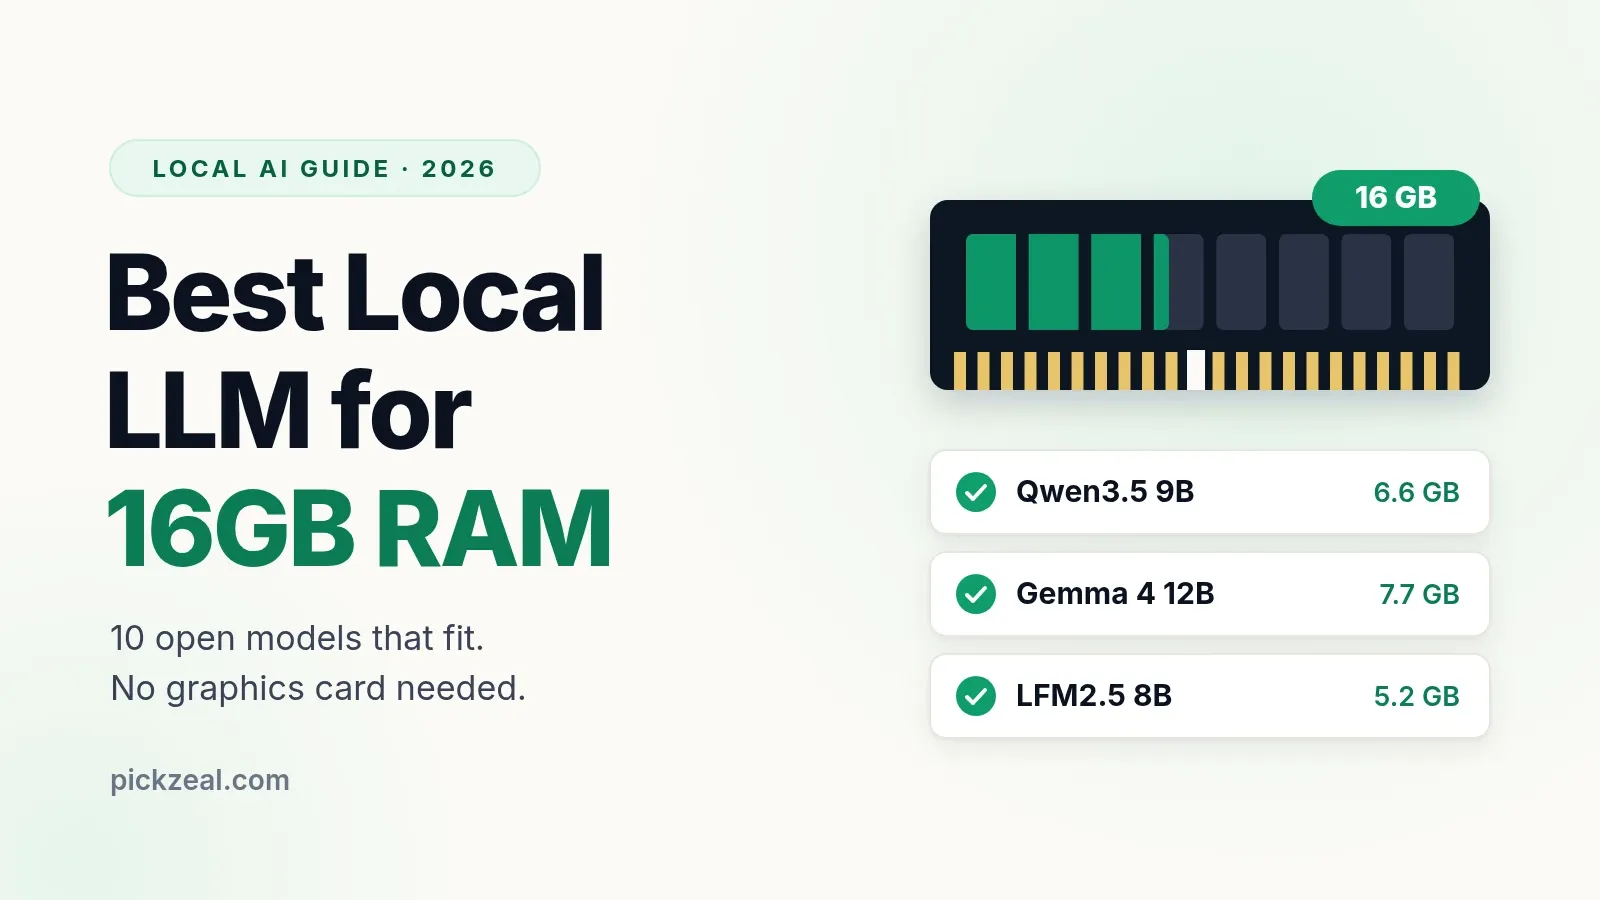
Best Local LLM for 16GB RAM: 10 Models That Fit (2026)
The best local LLMs for 16GB RAM and no GPU: 10 models that fit, real Ollama sizes, speed estimates, and the popular picks that only fit a 16GB GPU.
Topic: Local LLMs
A local LLM is a language model that runs on your own computer instead of on a company server. Your prompts never leave the machine, it works offline and there is no subscription.
Getting one running comes down to three choices: a model small enough for your RAM or VRAM, a quantized file format such as GGUF Q4_K_M that shrinks it to fit, and an app that runs it, such as Ollama, LM Studio or llama.cpp. The guides below start from the hardware you already have.
4 guides
21 min read
The best local LLMs for 16GB RAM and no GPU: 10 models that fit, real Ollama sizes, speed estimates, and the popular picks that only fit a 16GB GPU.
17 min read
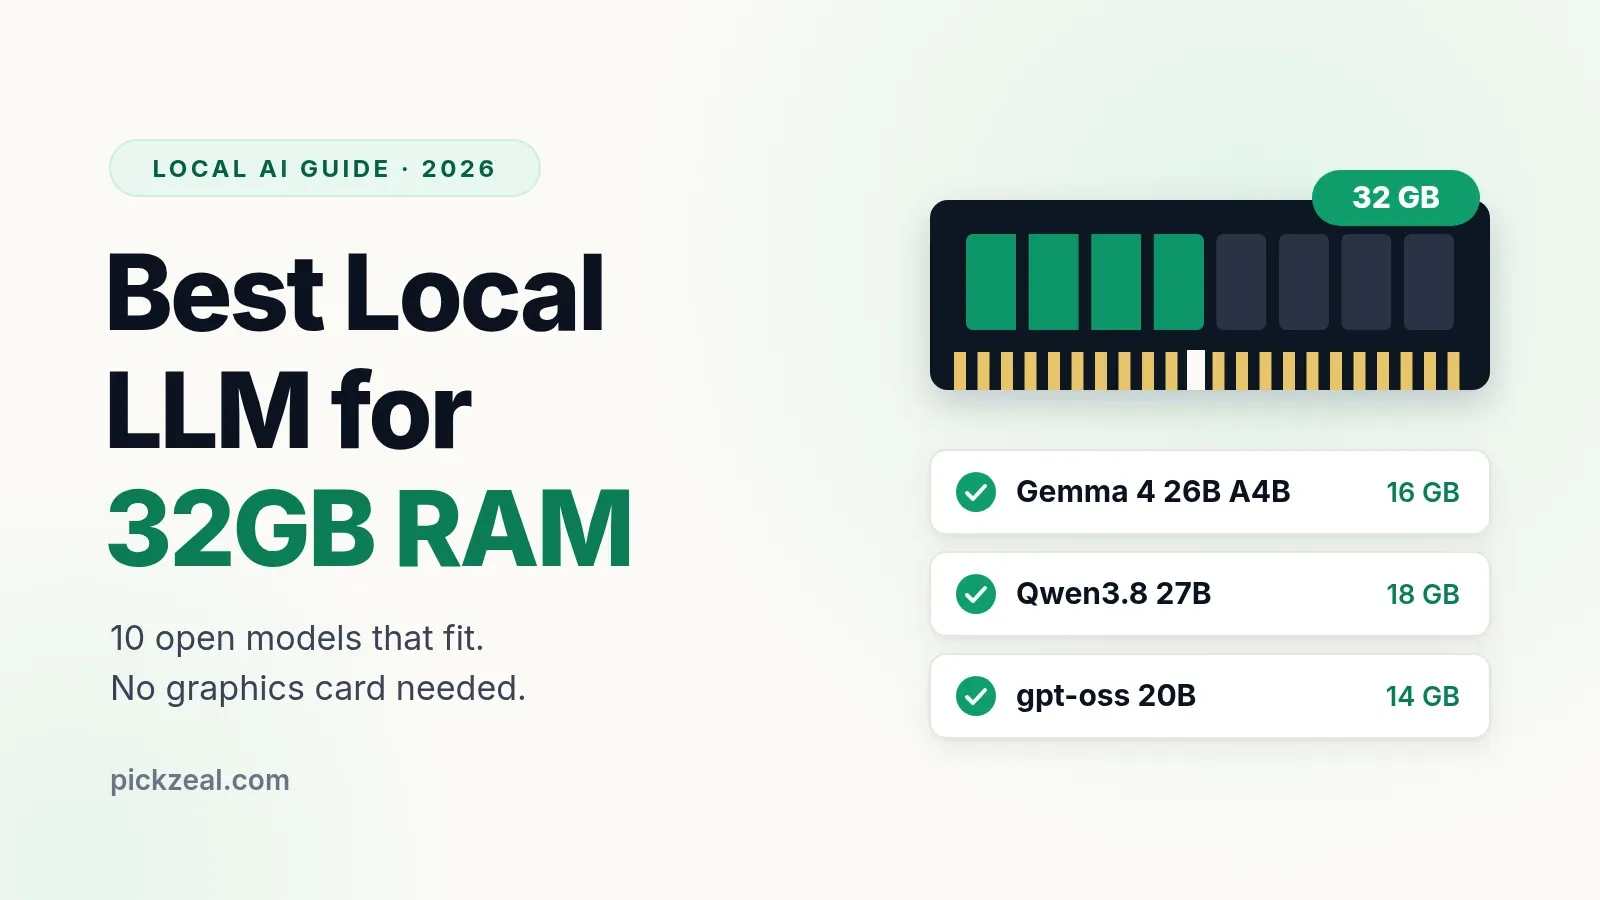
The best local LLMs for 32GB RAM and no GPU: 10 models that fit, real Ollama sizes, and why mixture-of-experts models run 5 to 10 times faster on a CPU.
12 min read
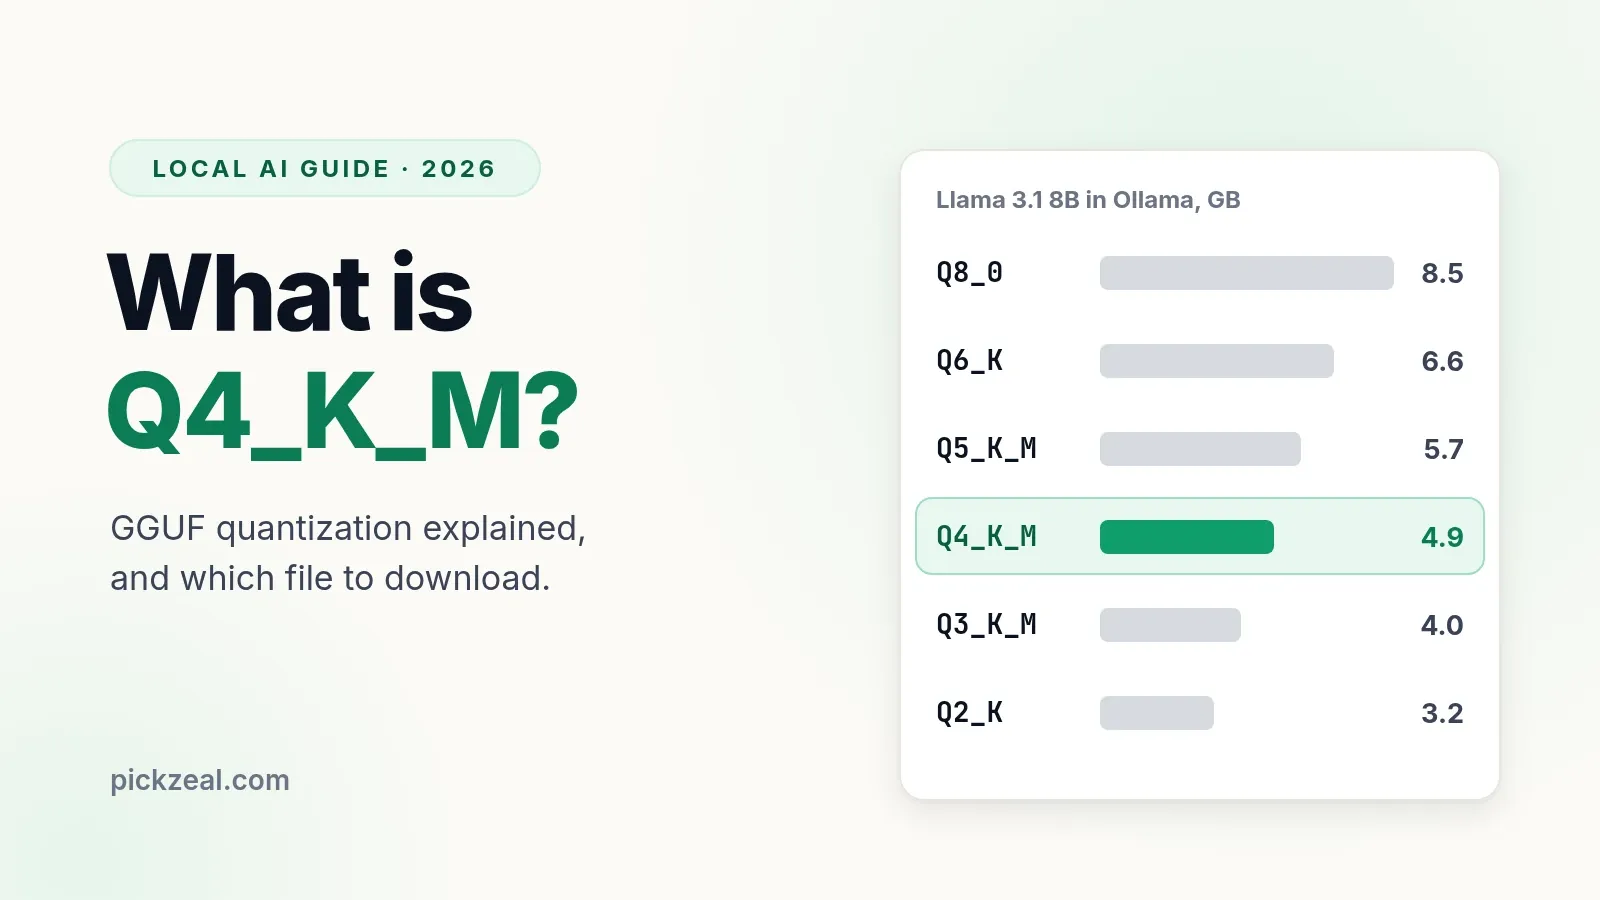
What Q4_K_M means in a GGUF file, how it compares with Q4_K_S, Q5_K_M, Q6_K, Q8_0, IQ4_XS and UD-Q4_K_XL, and which quantization to download for your RAM.
24 min read
The best open source LLMs for 8GB RAM and no GPU: 9 models that fit, real download sizes, speed estimates and Ollama setup for Windows, Mac and Linux.